Deploy a Custom Model#
After you onboard a custom model from Hugging Face or an S3 bucket, it appears on the Custom Models page — see the Model Catalog overview. Once the model is ready, you can deploy it as an inference service and connect to it like any other model in the project. This page covers deploying a ready custom model, what to expect while it starts, how to confirm the deployment is healthy, and the main things you can do with it afterward.
Before You Begin#
To deploy a custom model, onboarding must be complete: its card no longer shows an Importing or Onboarding status, and its Deploy button is enabled. See Onboard a Custom Model for information about the onboarding process and how to track its status.
You need access to a project with capacity to run the model. Deployments consume project resources (including accelerators), so make sure your project has enough quota available.
Decide which profile to deploy with. Every custom model has a Default profile from onboarding, and you can add named profiles that serve it on different hardware or tune it for a different performance metric. If you want a profile that does not exist yet, create it first — see Custom Model Profiles.
Deploy the Model#
In the sidebar, expand Models and select Custom Models.
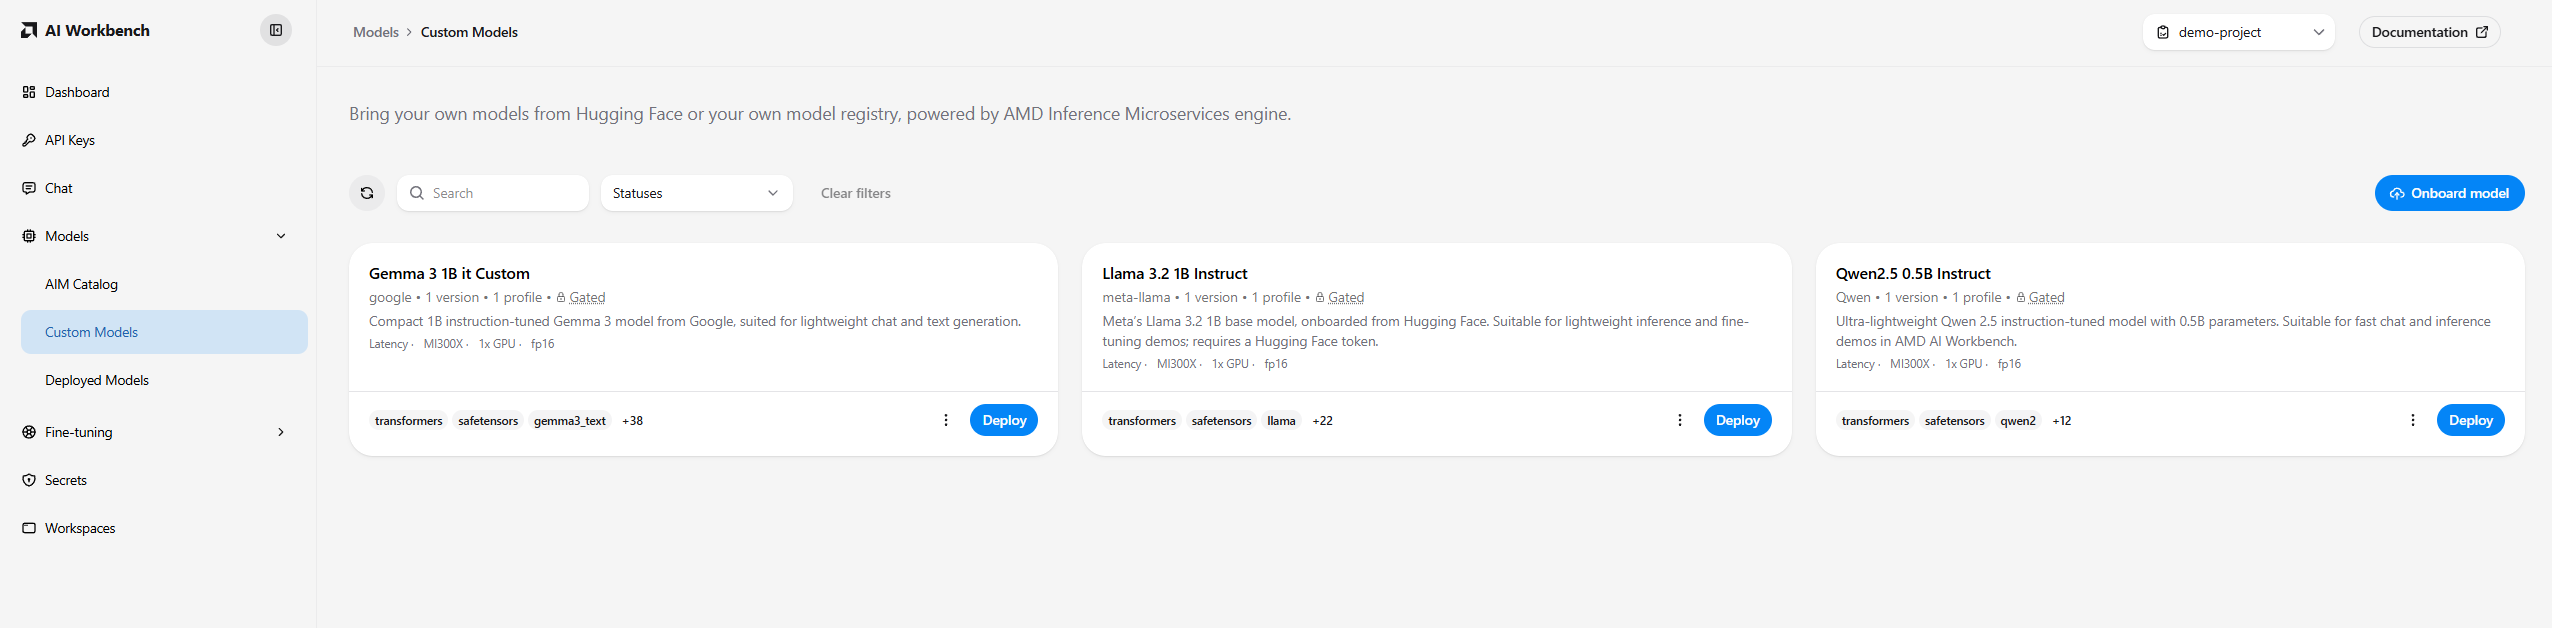
Find the model you want to deploy and select Deploy on its card.
- alt:
The Custom Models page listing onboarded models, each with a Deploy button on its card.
3. In the **Custom model deployment** drawer, review the model details and set the deployment options:
   - **Display name** — an optional, descriptive name for this deployment. If you leave it empty, the deployment uses a generated name.
   - **Profile** — the runtime configuration this deployment runs with: container image, accelerator, accelerator count, precision, performance metric, and any engine arguments or environment variables. The drawer preselects the model's **Default** profile. Choose a different one, or add a new profile inline, to serve the model on other hardware or tuned for a different metric. See [Custom Model Profiles](./inference/custom-model-profile-settings.md).
   - **Autoscaling** — optionally enable autoscaling so the deployment adjusts its replica count with demand. Autoscaling can only be enabled at deploy time. For details on the autoscaling options, see [Advanced Deployment Options](./inference/deployment-options.md#autoscaling).
4. Select **Deploy**.

The Workbench confirms that the deployment has started and begins bringing the model up in the background.

```{image} ../core-img/inference/custom-model-profiles-deploy-select.png
:alt: The Custom model deployment drawer showing the model details, the display name field, the Profile dropdown listing the available profiles, and the autoscaling toggle.
Note
The profile you choose is pinned for the life of the deployment. Editing that profile later does not change a deployment that is already running — to apply new settings, undeploy and deploy again. Because the choice is per deployment, you can run the same model twice with different profiles at the same time.
What to Expect After Deploying#
Deployment is not instantaneous. Before the model can serve requests, the platform schedules the workload, pulls the container image, and fetches model weights from the onboarded source. The first deployment of a large model can take several minutes.
You can follow progress on the Deployed Models page in the sidebar under Models, from the workloads table on the Dashboard, or by selecting Open details on the deployment. A deployment moves through these states:
Pending — the deployment has been accepted and is waiting to be scheduled.
Starting — the container is starting and the model is loading.
Running — the model is serving and ready to use.
Failed — the deployment did not come up. See Troubleshooting below.
You don’t need to keep the drawer open while the deployment starts.
Verify a Healthy Deployment#
In the sidebar, expand Models and select Deployed Models.
Find your deployment and check that its status is Running.
For more detail, open the deployment’s action menu and select Open details to open its workload detail page, where you can review the deployment’s components and inference metrics.
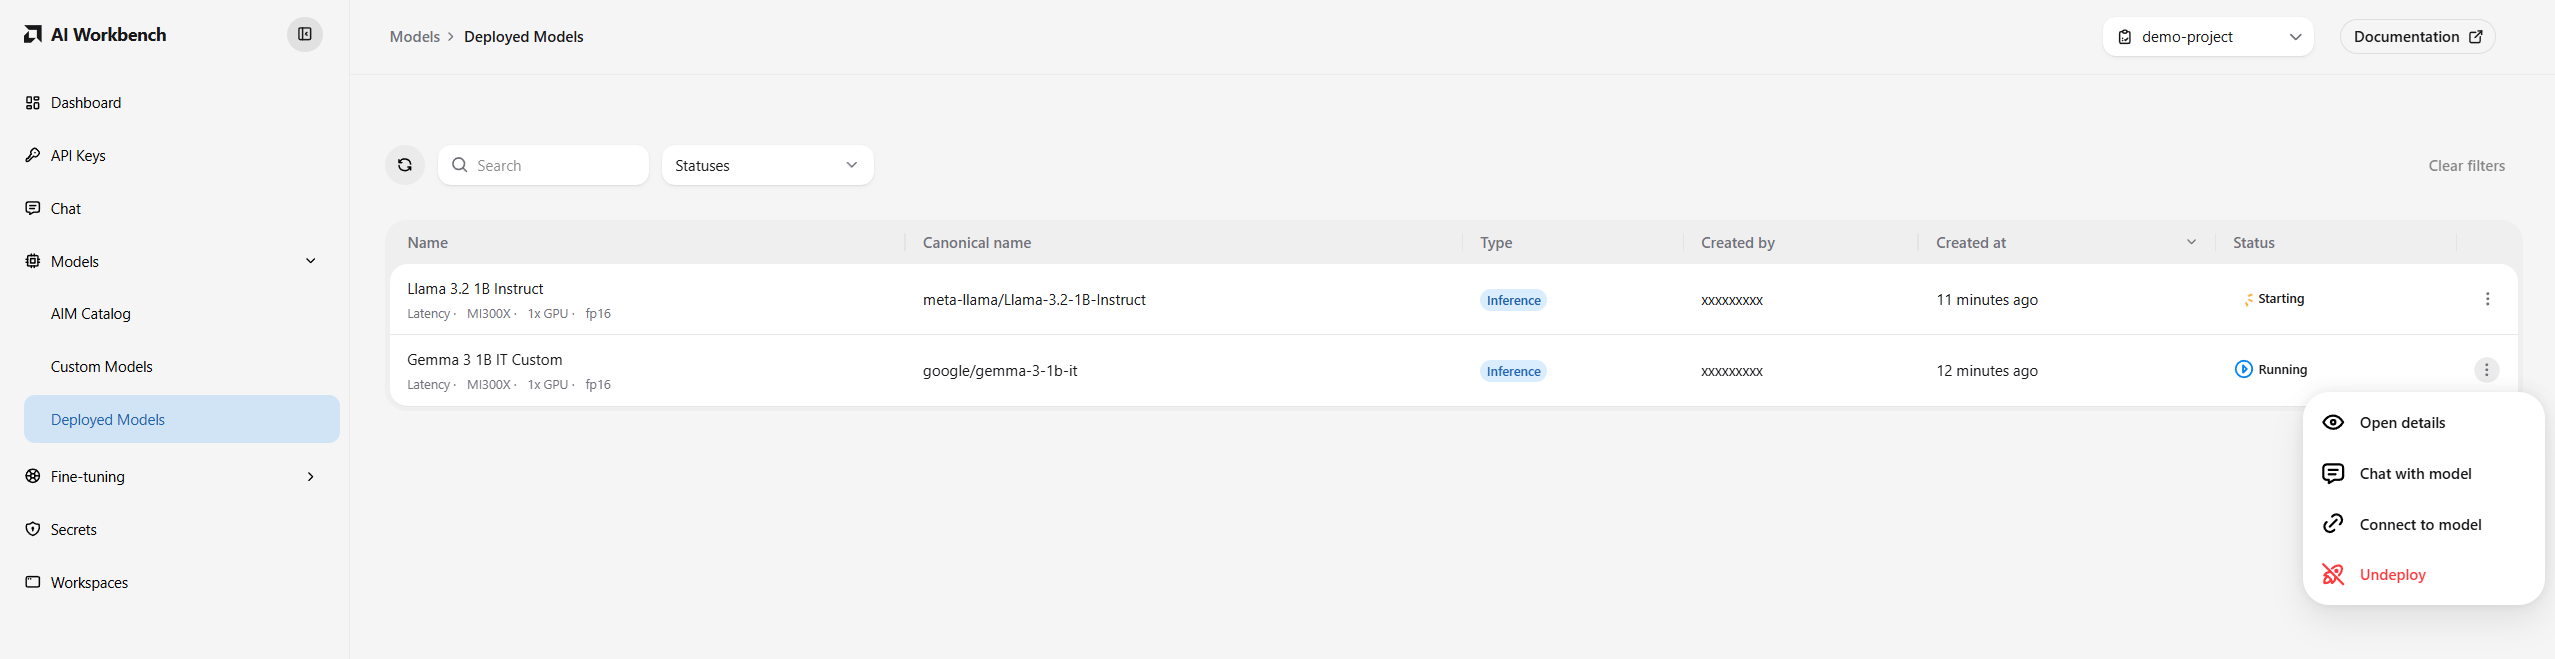
A deployment in the Running state is healthy and ready to receive requests. If it stays in Pending or Starting for a long time, or shows Failed, see Troubleshooting.
Work with a Deployed Model#
From the Deployed Models page, open a deployment’s action menu:
Open details — open the deployment detail page to review its components, status, and inference metrics. Available for any non-deleted deployment.
Undeploy — remove the deployment when you no longer need it. This stops the inference service and frees its resources; your onboarded model remains on the Custom Models page and can be deployed again later. Undeploying also releases the profile, so it can be edited or deleted again. Available for any non-deleted deployment.
When a deployment is Running, the menu also includes:
Connect to model — open the connection details (such as the model’s endpoints) you need to call the model from your own applications.
Chat with model — open the Chat page with the deployment selected, so you can try it interactively. Chat is available for deployments that support chat-style responses. In the Chat model list, custom model deployments are labelled with the profile they run, so you can tell apart two deployments of the same model.
Troubleshooting#
Deployment Stays in Pending or Starting#
A deployment can sit in Pending while it waits for resources, or in Starting while a large model loads. If it does not reach Running after a reasonable wait:
Confirm your project has enough available capacity (including accelerators) for the model. A deployment cannot start if the required resources are not available.
Open the deployment detail page through Open details to review its components for a more specific reason.
Deployment Failed#
If a deployment shows a Failed status, open its detail page through Open details to see why it did not start. Common causes include insufficient project resources, invalid or expired source credentials (for example, a revoked Hugging Face token or rotated S3 keys), or a profile whose accelerator, precision, or engine arguments the model cannot run with. After addressing the cause — for example adjusting the profile or deploying with a different one — undeploy the failed deployment and deploy the model again.
Chat Is Not Available#
The Chat with model action appears only for Running inference deployments that support chat-style responses. Connect to model is also available only while the deployment is Running. If you don’t see Chat with model, confirm the deployment is Running. If it is Running and Chat with model still isn’t offered, the model does not expose a chat-compatible interface — when the deployment is Running, you can use Connect to model instead to call its endpoints directly.